Introducing the finddatasciencejobs API: every DS, ML and AI role as JSON
A free data science jobs API. Pull every live data science, ML engineering and AI research role on the board as clean JSON — no contract, no sales call. Here's how it works and how to build on it.
Introducing the finddatasciencejobs API
We built finddatasciencejobs to answer one question well: where are the real data science, ML engineering and AI research jobs right now? We scrape them from company ATSes, dedupe them, and enrich each one with structured fields — skills, seniority, role type, a plain-English summary.
Until today, all of that lived behind the website. Now it's an API.
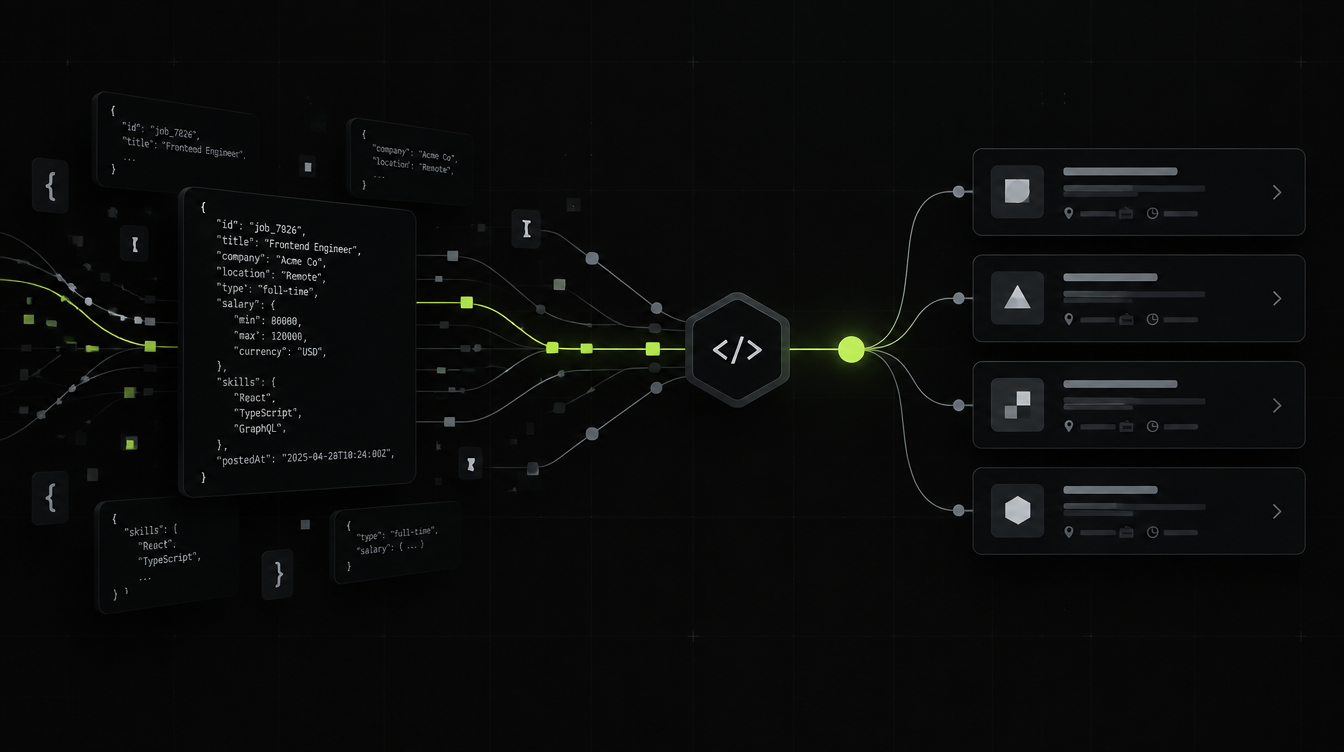
Every live role on the board is available as clean JSON at https://api.finddatasciencejobs.com/v1. Use it in your app, your newsletter, your Discord bot, or your own job board. It's free, there's no contract, and there's no sales call.
If you just want to see it work, this returns ten jobs right now, no key needed:
curl "https://api.finddatasciencejobs.com/v1/jobs?limit=10"
Why we're doing this
Most job data is either locked up or garbage. The big aggregators either don't have an API, charge enterprise money for one, or ship you a firehose of stale, duplicated, keyword-stuffed listings that you then have to clean yourself.
Our board is already narrow and already clean. It's only data science, ML and AI roles, every listing is deduplicated on ingest, and every one is enriched with the same structured schema. That's exactly the shape you want when you're building something on top of it — you shouldn't have to re-parse a description to find out whether a job is remote or what seniority it is. We already did that work, so the API just hands it to you.
The honest version: opening the data up is also good for us. If your newsletter or bot links back to the original posting, that's distribution we didn't have to pay for. So the deal is deliberately simple — you get clean job data for free, we ask for a link back. More on that below.
What you get per job
Each job comes back with:
- Title and company (with the company's website and logo)
- Location — country and cities — plus a remote flag
- Employment type, seniority, and role type (e.g. ML engineer, data scientist, data engineer, analyst, MLOps, research scientist)
- Skill tags extracted from the posting
- Salary range, where the employer actually published one
- A short AI-written summary of the role
- The full description
- The date it was posted
- A
urlback to the job's page on finddatasciencejobs.com
That last field matters for two reasons: it's where you send applicants, and it's the link the attribution terms ask for.
The endpoints
There are three, and you can get useful results from the first one without signing up for anything.
GET /jobs — list and filter roles
The workhorse. Returns the current set of jobs, filtered by whatever query parameters you pass:
Parameter | What it does |
|---|---|
| How many jobs to return |
| Only jobs posted on or after a date ( |
| Full-text search across the listing |
| Filter to remote roles |
| Filter by country |
| ML engineer, data scientist, data engineer, etc. |
| Junior, mid, senior, staff |
A newsletter that goes out weekly, for example, only wants what's new since the last send:
curl "https://api.finddatasciencejobs.com/v1/jobs?limit=100&since=2026-09-01" \
-H "X-API-Key: fdsj_your_key_here"
GET /jobs/{slug} — one role
Fetch a single job by its slug when you want the full record for a detail view.
POST /keys — get an API key
You can query /jobs anonymously, but a free key raises your daily allowance from 10 jobs to 500. Getting one is a single request:
curl -X POST "https://api.finddatasciencejobs.com/v1/keys" \
-H "Content-Type: application/json" \
-d '{"email":"you@example.com","site":"https://your-site.com"}'
The key comes back in the response and is not shown again — save it somewhere safe when you get it. From then on, pass it as an X-API-Key header.
Rate limits
We keep this deliberately plain:
Tier | Limit |
|---|---|
Anonymous (no key) | 10 jobs / day |
Free key | 500 jobs / day |
Higher | Talk to us |
The anonymous tier is there so you can test and prototype without committing to anything. The free key is enough to run a real newsletter or a small board. If you're building something that genuinely needs more, don't try to route around the limit with rotating keys — just email us. We'd rather know what you're building and say yes.
The one rule: attribution
The data is free. In exchange, we ask three things, and they're all about sending credit and traffic back to the source:
- Link back. Every job comes with a
urlon this site. If you display the job, link to that URL. - Name us as the source. Once per page is plenty.
- Send applicants to the job's page here. Don't strip the listing and route people elsewhere.
That's it. It's the same bargain that makes the whole thing sustainable: we do the scraping, deduping and enrichment; you get structured data for free; the original postings get the traffic they're owed.
What people are building with it
A few things this is a good fit for:
- A niche newsletter — pull everything
sinceyour last issue, filter toremote=trueor arole_type, and you have your content. - A Discord or Slack bot — post new senior ML roles to a channel as they land.
- Your own job board or aggregator — seed or supplement it with a clean, pre-enriched DS/ML feed instead of scraping from scratch.
- Analysis — the salary and skills fields make it easy to track what the market is actually asking for over time.
Start here
curl "https://api.finddatasciencejobs.com/v1/jobs?limit=10"
If that gives you what you need, grab a free key and go. Full parameter reference lives at finddatasciencejobs.com/api.
Building something with it? We'd love to see it — and if you hit the ceiling of the free tier, that's a conversation, not a paywall.